Fully Autonomous B2B Ad Management Versus Co-Pilot Tools That Still Need You
Autonomous agents act within set limits; co-pilots wait for human approval before moving.
An AI agent for B2B Google and LinkedIn Ads management needs the power to act across both channels and use pipeline feedback as well as suggest changes. Fully autonomous management differs from co-pilot tools in where human judgment sits. The choice determines how quickly campaigns learn, who owns the outcome, and how much work actually leaves the team’s plate.
Why the co-pilot versus autonomous agent question is not about automation depth
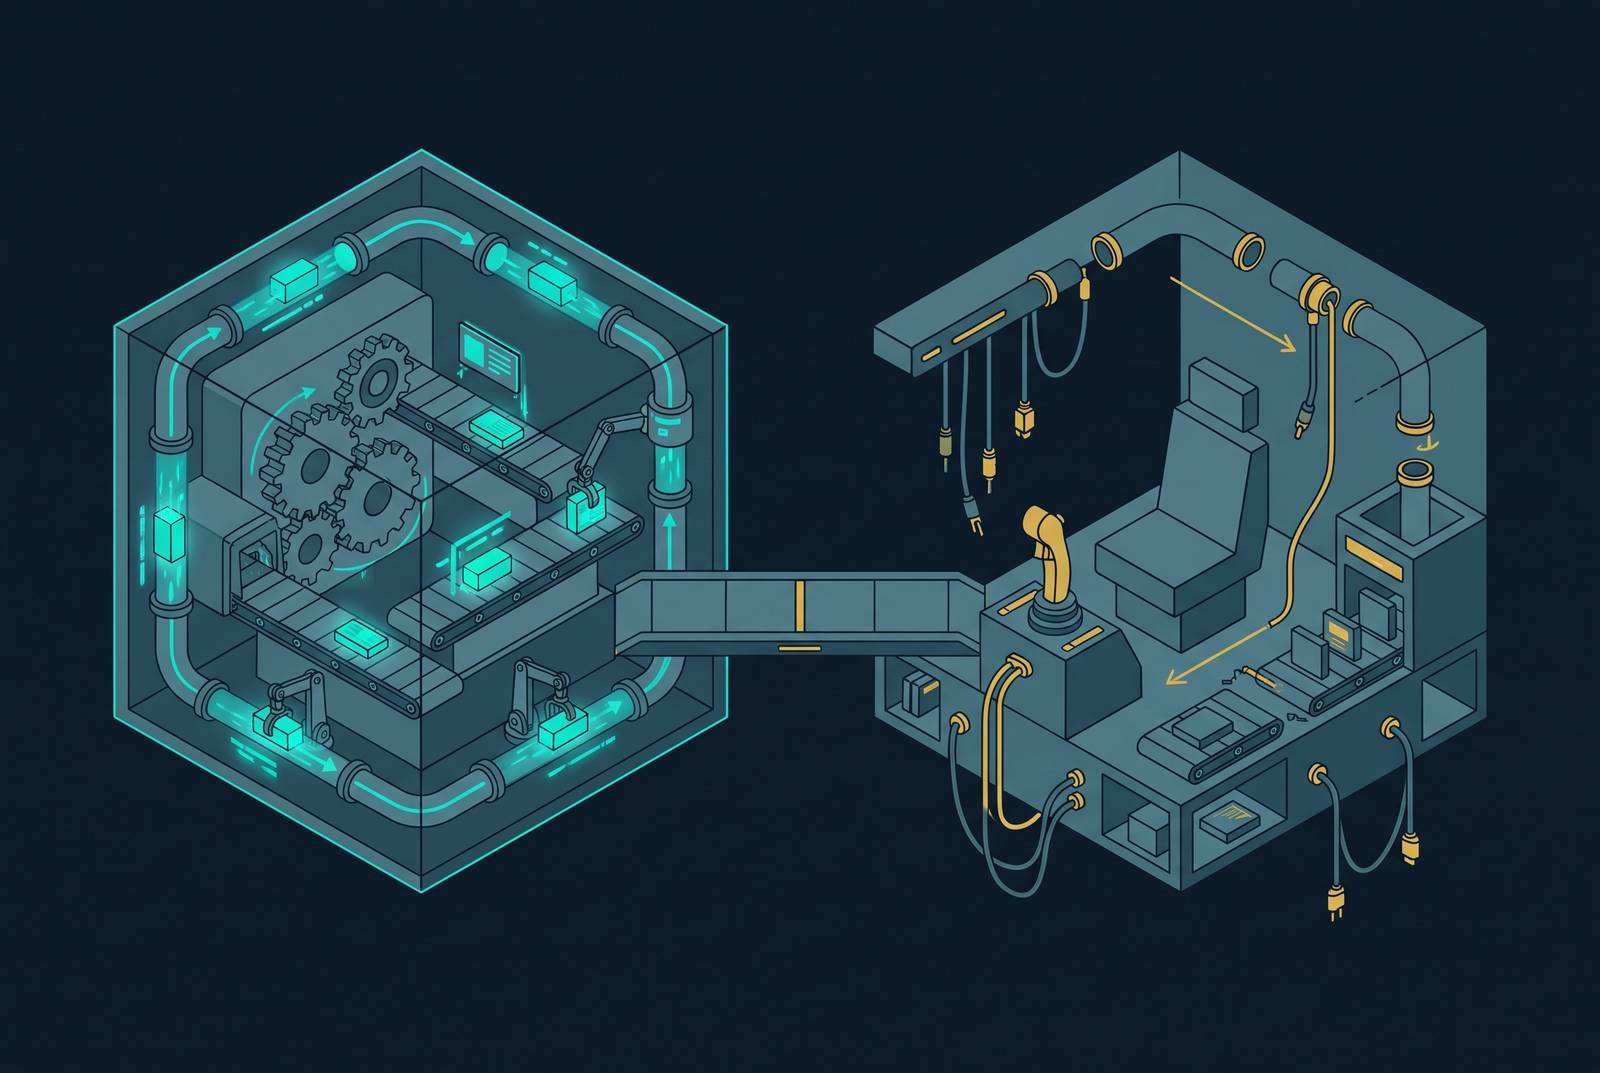
The market often presents automation as a dial, with a helpful chatbot at one end and a self-running ad program at the other. That framing hides the important distinction. A co-pilot makes something a person must check and approve before any action is taken, while an autonomous agent acts within limits a person has set. The human is either the campaign’s operator or the system’s governor.
Co-pilots improve access to information but leave a bottleneck at execution. They wait for questions, produce recommendations, and hand the work back. At low campaign volume, that arrangement can be useful because the person has time to examine the answer and act. As campaigns and signals multiply, however, more output demands more human decisions.
What does an AI agent for B2B ad management actually do differently at the execution layer?
An autonomous agent is given a business objective and works out the steps to reach it without a person directing it all the time. The objective might be to reduce cost per qualified lead. Within its authority, the agent determines channel mix, bid strategy, creative rotation, and audience adjustments, then changes course using live performance data. Unlike preset if/then rules, it plans a multi-step workflow. Unlike a chatbot, it does not finish its job by handing over an answer.
Multi-agent architectures divide that work among specialists. One agent handles creative, another manages bids, and another analyzes performance, while an orchestrator directs them through a shared coordination layer. This separates specialist work without making a human relay every finding. The distinction is whether agents direct execution across targeting, bidding, creative, and budget pacing, or merely support supervised automation.
Platform-native tools automate a lot of work, but they can act only inside their own ecosystems. Google AI Max automates search term matching, text customization, and final URL expansion, while budget settings and bid strategies remain standard Search campaign controls managed by the advertiser. Meta Advantage+ automates audience targeting, ad placement, and budget allocation across its campaign structures. These are meaningful execution capabilities. The human still designs the campaign, and neither platform supplies coordination across Google and LinkedIn.
Standalone agents can work across more than one platform. Albert by Zoomd autonomously handles budget allocation, creative testing, and bid optimization, while Zoomd positions it as working with human marketers who retain strategic oversight. That distinction prevents “autonomous execution” from being mistaken for “no human responsibility.” It also limits what a buyer can conclude from a product category alone. Tactical autonomy alone does not show that an agent fits a B2B pipeline or covers all the work on Google and LinkedIn.
Why B2B paid media specifically strains the co-pilot model
Sales-led B2B introduces a delay between what advertising can measure quickly and what the business wants to know. Sales cycles can run for many months. Last week’s click data therefore says little about which campaigns will lead to deals, even if it gives a co-pilot plenty to talk about. Buying committees add another complication because a platform-reported conversion captures a single event within the multi-stakeholder buying process. A tidy dashboard can describe a very untidy journey.
GA4 engagement metrics, read with ad platform data, offer a better interim proxy for pipeline quality. Time spent on pricing, demo request, and case study pages can help show which visits are high-intent while sales outcomes take shape. But a proxy is still a proxy. CRM integration and offline conversions close the loop by teaching the bidding system what a qualified lead looks like. Without that connection, optimization can reward form submissions without accounting for which leads close.
Channel roles make those signals harder to interpret separately. Google Search comes first for high-intent demand capture, while LinkedIn is the main channel for pipeline generation with buying committees that are high-ACV, named-account, and title-driven. Google can then catch late-stage search. LinkedIn’s materially higher CPMs make sense when company-level and job-title targeting justify the premium.
That creates an execution problem as well as an analysis problem. A co-pilot can recommend moving budget, but a person must still interpret the recommendation and make the change. An autonomous system with the relevant authority can reallocate spend, test a LinkedIn creative variant, and monitor both channels. It can also use closed-loop signals continuously without manual handoffs. The advantage of a product labeled “agent” depends on those connections actually existing.
How the location of decision authority shapes pipeline outcomes
When a human must approve every action, learning moves at the speed of that person’s availability. A co-pilot can identify an audience insight or a weak result in creative performance data, but someone must decide what happens next and preserve the lesson for later. That handoff limits the feedback loop. An autonomous system can accumulate evidence about audiences, creative, and prior decisions so that the next action starts from the history already available.
The quality of that evidence is crucial. A system connecting creative, landing pages, attribution, and bid data can distinguish a bid problem from a constraint elsewhere in the path to pipeline. Otherwise, optimization risks adjusting the easiest control while leaving the actual constraint unresolved. If the landing page is the constraint, another bid recommendation leaves the central problem untouched. Diagnosis gives execution a useful direction.
Attribution is where this distinction becomes especially consequential. Platform-reported ROAS becomes less reliable as automation deepens because an algorithm can credit itself for conversions it did not cause. B2B buyers also pass through many touchpoints, so one attribution model is too little to cover the journey. Media mix modeling fits the work of budget allocation each quarter, while data-driven attribution fits the work of optimization for each campaign. Incrementality testing addresses the separate question of causation, distinguishing genuine lift from credit claimed after the event.
An autonomous system with closed-loop attribution can run an incrementality test, interpret the result, and adjust allocation without waiting for a human handoff. Causal measurement requires autonomy to be paired with the testing capability and the right outcome signals. The same condition applies to creative, which becomes a primary source of differentiation as targeting and placement move to similar algorithmic infrastructure. Making variants gives the system options, and rotating them and comparing pipeline outcomes shows what those options can do.
What “fully autonomous” actually requires to be safe at scale — governed autonomy versus reckless automation
When a system can act without human approval, there is good reason to fear it will spend money badly at machine speed. That objection deserves more than a reassuring adjective. Governed autonomy places spend caps, approval gates, and audit trails around execution that is capable but not unconditionally trusted. What vendors claim can be far from what others have checked and shown to work. Delegation therefore needs defined boundaries.
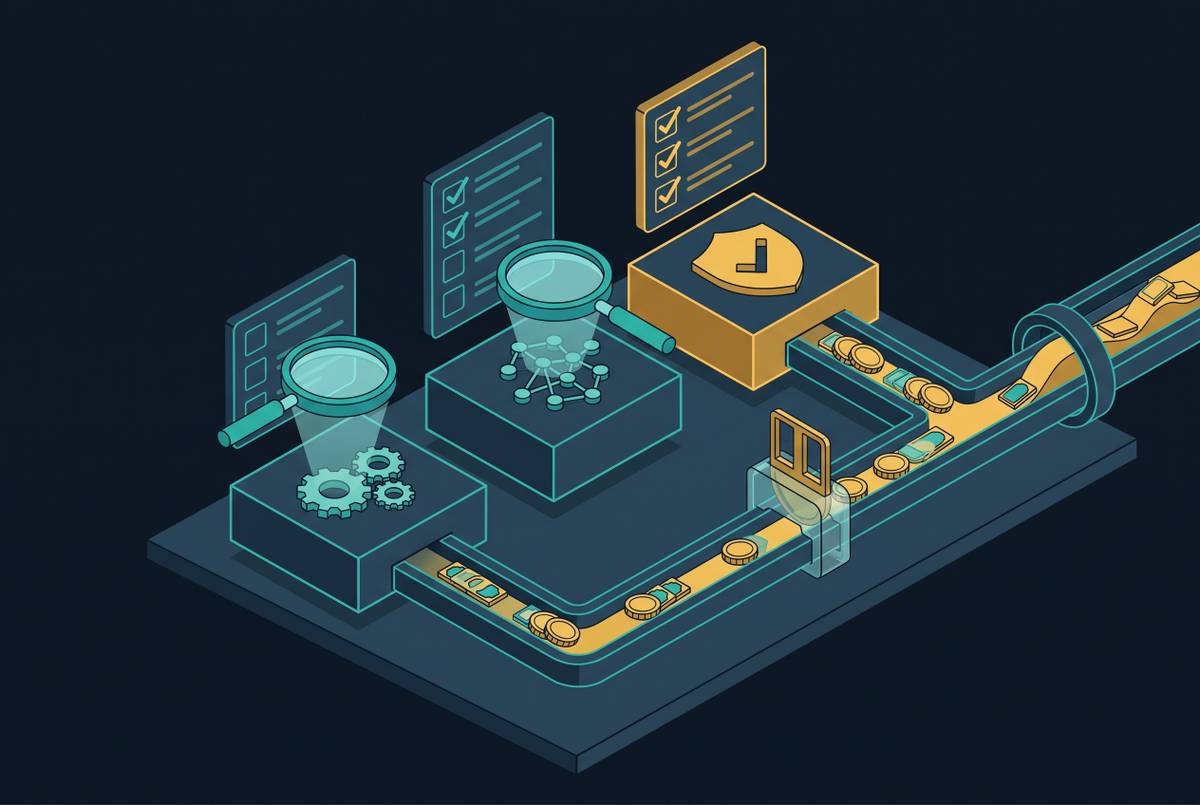
Those boundaries have concrete forms. Budget validation rules stop campaigns from launching with the wrong spend caps, while naming taxonomy enforcement keeps campaigns organized in the same way. Audit trails record who changed what and when. Escalation triggers flag decisions that fall outside the set limits and need human judgment. Approval gates belong at those boundaries, rather than in front of every routine bid adjustment or creative rotation.
The division follows the nature of the decision. ICP definition, a strategic channel shift, and whether a weak quarter reflects poor creative or a market signal involve consequential ambiguity. Those decisions deserve human judgment. Routine execution within agreed parameters does not benefit automatically from another person clicking “approve.” Human oversight is most useful when it supplies judgment the system should not own, rather than merely slowing work the system is authorized to perform.
A budget reallocation within an agreed channel strategy is therefore different from rewriting that strategy. Similarly, diagnosing a weak creative variant is different from deciding that the market no longer wants the offer. Governance makes those distinctions explicit. Set tight guardrails and let the agent execute inside them, with escalation when a decision exceeds its remit.
How the model you choose determines how much marketing burden actually leaves the team’s plate
Co-pilot tools can shorten individual tasks without reducing the number of decisions a team owns. Someone still evaluates the output, approves the action, and makes it happen. Review is work in a different outfit. Across Google, LinkedIn, audiences, creative variants, and conversion events, recommendations can accumulate faster than the team can process them.
Changing the supplier does not necessarily remove that bottleneck. An in-house team owns execution decisions directly, an agency distributes them across account managers, and DIY software requires the customer to operate it. Each setup needs someone to link the decisions made to the results they bring. When poor performance prompts the agency and internal team to point at each other’s territory, diagnosis gives way to negotiation. That slows the very decisions performance marketing depends on.
Full delegation with a named expert governing the system changes the allocation of responsibility. The system executes continuously, while the expert owns exceptions, strategic judgment, and accountability for outcomes. There is a clear place for unresolved questions to land. Instead of assigning the team another stream of recommendations, the arrangement assigns someone responsibility for the whole connected program. That is a transfer of work.
A fee tied to media spend creates an incentive to recommend more spending precisely when the diagnosis might call for something else. A flat retainer decoupled from spend removes that particular incentive. It aligns the governance model with pipeline and revenue. The distinction is especially important when the real constraint is creative, a landing page, or an attribution gap, because the appropriate response may be to spend less.
How to assess which model fits a given program’s stage and complexity
Start with the program’s actual constraint. Co-pilots fit when campaign volume is manageable, the team has genuine time to review and act, and faster access to information is the main need. In that setting, retaining execution authority is workable. Platform-native autonomy fits when most work stays inside one ecosystem and the team can control spend and creative inputs. It does not supply cross-channel coordination or automatically close the loop to pipeline.
Standalone autonomous agents fit teams that want to delegate cross-channel execution but retain the capacity to govern strategic direction and hold the system accountable. Full delegation with a named expert fits when the team does not want to own execution decisions and needs accountability across the whole program. Neither choice removes the need for governance. For a Google and LinkedIn buyer, the relevant criteria are authority to act across both channels, CRM and offline-conversion feedback, diagnostic coverage, and named responsibility for exceptions. A vendor’s broad autonomy claim is not a substitute for those capabilities.
Signs of a mismatch are often visible in the work already waiting. Review queues grow faster than the team can clear them, or attribution stops at platform conversions, leaving deal outcomes untracked. Poor performance cannot be traced to creative, landing pages, attribution, or bid strategy because those layers remain disconnected. Ownership can also disappear when an agency turns passive, a contractor waits for instructions, or an in-house owner leaves. The final diagnostic is not how much automation the program wants, but where decision authority belongs and who is accountable for the outcome.